Skip to content

Data Engineering · Analytics · Data Science

Krishna MihirTatavarthi

Pipelines that scale, data you can trust

About

I turn raw data into things people can trust in production: pipelines, dashboards, and models that drive real decisions.

I work across the full data lifecycle, with 3 years of experience in data engineering, analytics, and data science, and I completed my MS in Computer Science at UMBC (GPA 3.93) in 2026. I build the pipelines that move and validate data, analyze it to answer business questions, and model it when a prediction is worth more than a report.

At Maroon Group I turn 100K+ daily hardware test records into validated datasets and made Athena queries up to 73% faster. Improving Mode Analytics dashboards is part of that daily work: I sit with the people who depend on them, hear what slows them down, and turn that feedback into faster queries and clearer reports. At VelocitiPM I built Kafka and SNS/SQS pipelines feeding 30+ AI agents.

My roots are in analytics. At Red.Health I analyzed fleet, trip, and financial data across 400+ ambulances and 550+ cities, building the pricing model and Tableau reporting that leadership used to make decisions. That is why I care as much about who uses the data as about how it gets there.

On the data science side, I've published ML research on detecting machine-generated text (IEEE) and health insurance fraud (IJARESM), and as a Graduate Research Assistant at UMBC I lifted pulsar detection recall from 82.3% to 89.6% on heavily imbalanced telescope data. Rigorous modeling with a real-world stake is the work I enjoy most.

Krishna Mihir TatavarthiRECLIVE
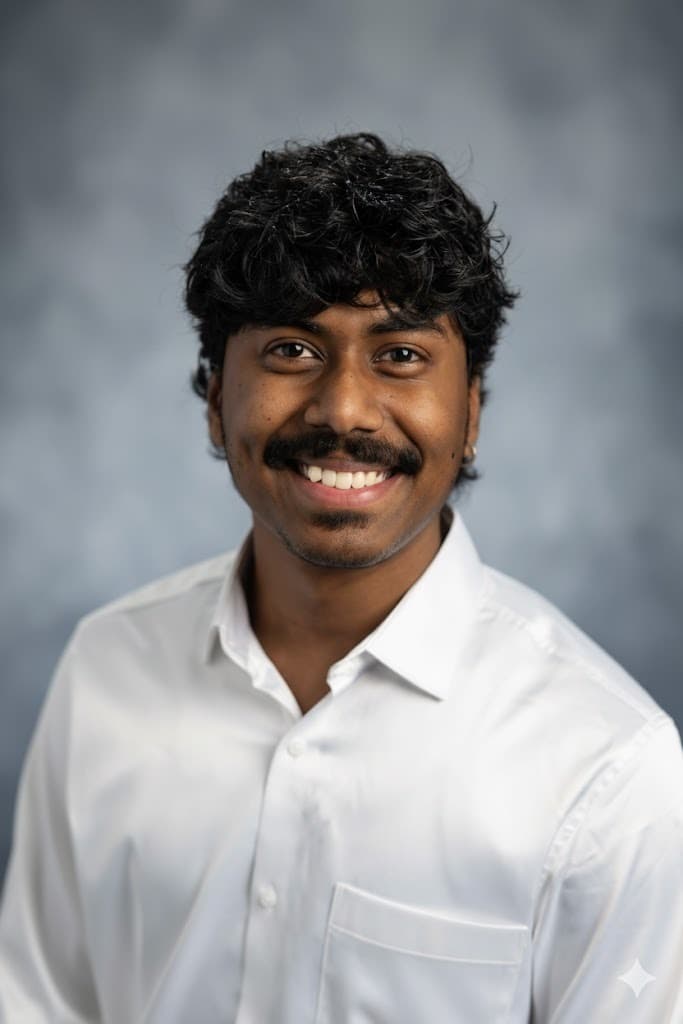
KM.T / PortraitBaltimore, MD
Experience
3 years · Engineering, analytics, data science
MS Computer Science
UMBC · GPA 3.93 · 2026
B.Tech Computer Science
SRM University AP · 2024
Research
2 papers published · IEEE, IJARESM
Certifications
Azure Fundamentals · Power Platform Fundamentals · Amazon ML Summer School
Based in
Baltimore, MD

Stack

  • Python
  • SQL
  • PySpark
  • R
  • JavaScript
  • Bash
  • Java
  • Pandas
  • NumPy
  • Apache Spark
  • Apache Kafka
  • Apache Airflow
  • dbt
  • ETL/ELT
  • Apache Iceberg
  • Data Modeling
  • Hadoop
  • AWS S3
  • AWS Glue
  • AWS Athena
  • AWS Lambda
  • AWS SNS/SQS
  • AWS EC2
  • GCP BigQuery
  • GCP Vertex AI
  • Snowflake
  • Azure
  • PostgreSQL
  • Supabase
  • MongoDB
  • Tableau
  • Power BI
  • Mode Analytics
  • Excel
  • KPI Reporting
  • A/B Testing
  • Cohort & Funnel Analysis
  • SPC/CPK
  • scikit-learn
  • PyTorch
  • TensorFlow/Keras
  • Feature Engineering
  • Imbalanced Learning (SMOTE)
  • Model Evaluation
  • Hugging Face
  • Transformers
  • LangChain
  • LangGraph
  • Anthropic Claude
  • Terraform
  • Docker
  • Kubernetes
  • Git
  • CI/CD

Projects

Real-time observability for data pipelines that catches bad data and failed runs before anyone downstream notices.

  • Engineered a data-quality monitoring platform with FastAPI, PostgreSQL, Airflow, and dbt on a bronze → silver → gold medallion design, handling 10,000+ events per day at sub-200ms latency.
  • Automated quality checks flag and catch bad data before it propagates downstream; a live Next.js dashboard streams pipeline health over WebSockets with anomaly alerting.
  • Containerized with Docker and shipped through Kubernetes with GitHub Actions CI/CD, cutting failure detection from hours to under 10 seconds.
10k+
events / day
<10s
failure detection
<200ms
event latency
Next.jsFastAPIPostgreSQLAirflowdbtDockerKubernetes

Experience

  1. Maroon Group, Inc

    Aug 2025 – Present
    Data Engineer · Miami, FL
    • Built AWS Glue-scheduled pipelines with Python and PySpark that transform 100K+ daily hardware test records across 80+ tables into validated datasets stored in S3 and queried through Athena.
    • Improved Athena query runtimes by up to 73% with partition pruning, early filtering, optimized joins, and Iceberg tables, extending reporting history from 3 to 6 months.
    • Engineered reusable test-data workflows across 10+ reporting pipelines using S3, AWS Glue, PySpark, and Athena, supporting test-quality and performance analysis across 23 LIDAR test plans.
    • Reduced exploratory SQL development time by 60% by integrating Anthropic Claude with schema metadata and join relationships to generate multi-table Athena query drafts across 80+ tables.
    PythonPySparkAWS GlueAthenaS3IcebergAnthropic Claude
  2. VelocitiPM

    Feb 2026 – Jun 2026
    Data Engineer · Phoenix, AZ
    • Architected event-driven data pipelines using Python, Go, Kafka, AWS SNS/SQS, and Lambda, supporting 12+ workflows across 30+ AI agents while reducing P95 latency by 85%.
    • Developed end-to-end ETL/ELT and RAG workflows covering ingestion, validation, model registry, automated re-indexing, and monitoring, cutting incident resolution time from six hours to 30 minutes.
    • Enabled initiative scoring, theme linking, document ingestion, and structured AI-generated artifacts by designing PostgreSQL and Supabase data models, RPCs, and validation rules.
    • Standardized AWS infrastructure with Terraform and CI/CD, enabling reproducible deployments and increasing release cadence by 4x.
    PythonGoKafkaAWS SNS/SQSLambdaSupabaseTerraform
  3. UMBC

    Jan 2025 – May 2025
    Graduate Research Assistant · Baltimore, MD
    • Conducted pulsar candidate classification research on the HTRU2 radio telescope survey dataset in coordination with Dr. Milton Halem (formerly of NASA), building an end-to-end ML pipeline with SMOTE-based imbalance handling that lifted recall from 82.3% to 89.6% at 0.97 ROC-AUC.
    • Validated the trained models beyond the benchmark dataset in collaboration with astrophysicist Gnanesh (postdoctoral researcher), who stress-tested them on independent observational data where the models held up at 91% accuracy.
    Pythonscikit-learnPandasSMOTE
  4. Red.Health

    May 2022 – May 2024
    Data Analyst · Hyderabad, India
    • Achieved 85% fleet utilization by analyzing 100K+ trip and vehicle records with SQL, Python, and PySpark to identify coverage gaps and optimize scheduling across 400+ ambulances.
    • Increased product margin to 31% by building a cost-per-kilometer pricing model in SQL and Python, incorporating fuel, maintenance, driver, vehicle, and route costs.
    • Contributed to a 19% increase in profitability by integrating trip and financial data to analyze cost-per-trip and revenue margins, driving pricing and cost-control decisions with executive leadership.
    • Centralized KPI reporting across 550+ cities and 300+ hospitals by transforming fleet, trip, financial, and customer data with SQL, Python, and PySpark into interactive Tableau dashboards.
    SQLPythonPySparkTableau

Contact

Open to data engineering, data analyst, and data scientist roles. If you need pipelines, analysis, or models that people can trust, let's talk.